When AI decides who deserves help
29 September 2026
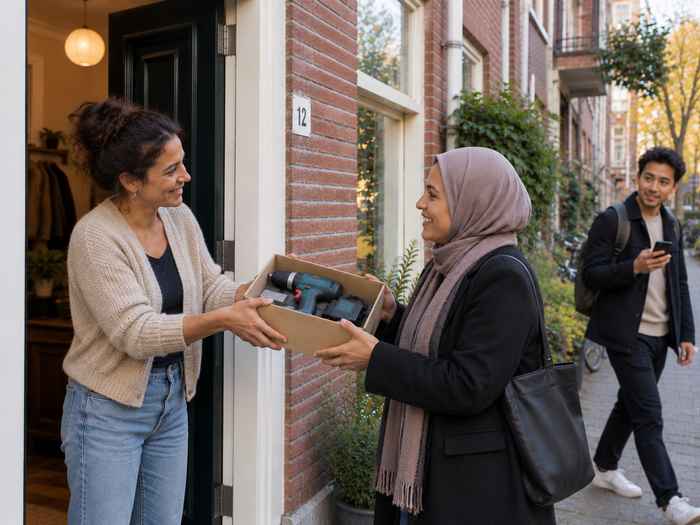
Such differences in answers can have real consequences: the social rules these systems apply can affect whether cooperation thrives or breaks down over time. As AI is increasingly used to offer advice, moderate online spaces and assess behaviour, understanding the values built into its judgements becomes more important.
In a study published in PNAS Nexus, researchers from the Social Intelligent Artificial Systems research group at the Informatics Institute examined the social rules used by 21 large language models (LLMs). The research was led by Alexandre S. Pires, with Laurens Samson, Sennay Ghebreab and Fernando P. Santos. The models largely agreed that helping a person with a good reputation is positive, and that refusing to help them is negative. But they differed sharply when judging actions towards someone with a bad reputation.
Why reputation matters
The drill example illustrates why reputation is central to cooperation. On a neighbourhood-sharing platform, people may be more willing to lend to neighbours with a record of helping others, and less willing to lend to those who have not. This is known as indirect reciprocity: cooperation is sustained because people gain or lose a good reputation through how they treat others.
The researchers wanted to understand whether LLMs apply social norms that could maintain cooperation through reputation. They presented the systems with 43,200 fictional scenarios in which one person either helped another person or chose not to. The models were then asked whether the person acting should receive a good or bad reputation. The scenarios varied in their context, wording and the names used.
While the models showed broad agreement in some situations, they did not follow one shared rule. Some judged helping as good regardless of the other person’s reputation. Others considered it acceptable to withhold help from a person described as having a bad reputation. Even different versions within the same model family could apply different norms.
Different norms, different outcomes
The team then examined what these differences could mean in practice. Using an evolutionary game-theory model, they simulated a population in which people repeatedly decide whether to help one another, using the other person’s reputation to guide that decision. Their actions also affect their own reputation, shaping whether others are likely to help them in future.
The simulations showed that the same social norms can have different effects depending on whether people agree about who is trustworthy. When everyone shares the same view of someone’s reputation, more detailed rules, such as treating a refusal to lend the drill differently depending on the borrower’s record, can help cooperation to grow. But when people disagree about reputations, simpler rules can work better because they do not depend on everyone seeing a person in the same way.
The researchers also tested whether prompting could guide models towards norms that encourage cooperation. Instructions that clearly stated the intended goal produced the most consistent results, although their effects still varied between models.
The findings show that it is not enough to check whether an AI gives a sensible answer in a single case. Developers also need to examine the broader rule a system applies across different situations – for example, whether it sees refusing help to someone with a poor reputation as unfair or justified. The researchers suggest that their framework could be used to test future models for such patterns before they are used to advise, moderate or assess people.